Data leakage: water escaping from a glass vessel

How to Detect Data Leakage: Signals, Tools and a Detection Checklist

No prevention programme is perfect. Access gets granted that shouldn’t be, a storage bucket is left public, a test database is copied to a laptop. What separates a minor incident from a major breach is often how quickly the organisation notices. Many leaks are discovered months later, and frequently by someone outside the organisation: a customer, a researcher or a regulator.

This guide is for security, data and platform teams who need to find leaks, not just define them. It covers the signals that point to a leak, six practical detection methods, the main categories of tools, how to find sensitive data hiding in test environments, what to do when you find a leak, and a detection checklist. For background on the causes of data leakage, start there.

Note: this article is about data leakage as a security problem. In machine learning, “data leakage” means information from outside the training set slipping into a model, which is a different topic.

Why Detection Matters

Leaked data does damage for as long as it stays exposed. A public bucket found in a day is an incident; the same bucket found after a year is a breach report, a regulator conversation and a customer notification exercise. Detection shortens that window. It also tells you whether your prevention controls are working, because every leak you find points to a gap you can close.

Signs of Data Leakage

Leaks rarely announce themselves. These are the signals worth watching for, inside and outside the organisation.

Inside the organisation

  • Unusually large downloads, exports or query results, especially from people who don’t normally pull that much data.
  • Access at odd hours, from unusual locations, or from accounts that should be dormant.
  • New public or “anyone with the link” sharing on files and folders that hold sensitive data.
  • Emails with sensitive attachments sent to personal addresses or unknown external domains.
  • Uploads to unsanctioned cloud storage, file-sharing sites or public AI tools.
  • Copies of production databases appearing in places they shouldn’t, such as developer machines or new non-production servers.

Outside the organisation

  • Your data, domains or employee credentials appearing on paste sites, breach forums or dark web marketplaces.
  • Storage buckets, databases or code repositories belonging to you found exposed to the internet.
  • Customers receiving phishing that uses details only you should hold.
  • Planted canary records or tokens being used or accessed.

Six Ways to Detect Data Leakage

1. Know where sensitive data lives

You cannot detect a leak of data you don’t know you hold. Data discovery and classification tools scan databases, file shares and cloud storage for personal, financial and health data and label it. Every other detection control depends on this map, because it tells monitoring tools what to watch and where.

2. Monitor data movement

Data loss prevention (DLP) tools inspect data as it moves through email, web uploads, endpoints and cloud services, and flag or block sensitive content leaving approved channels. Cloud access security brokers extend the same idea to SaaS applications. Tune DLP rules to your classified data, and start in alert mode so you learn normal behaviour before you block anything.

3. Audit access and data flows

Database activity monitoring records who queried what, and when. Feed those logs, together with identity, file-access and cloud audit logs, into a SIEM, and use behaviour analytics to spot deviations: a service account suddenly reading a whole customer table, or a user exporting far more than usual. Regular access reviews catch the slow problem of permissions that have quietly grown.

4. Scan for exposed storage and code

Cloud security posture management tools continuously check for public buckets, open databases and misconfigured sharing. Repository scanning catches credentials, keys and sample data committed to source control. These are some of the most common leak paths, and they are cheap to check automatically.

5. Monitor external sources

External exposure monitoring watches paste sites, breach forums, dark web markets and public code platforms for your domains, credentials and data. Breach notification services alert you when employee or customer accounts appear in known breaches. This is often how organisations first learn of a leak they missed internally.

6. Plant canaries

Canary records, also called honeytokens, are fake but realistic entries placed in databases, files and test data sets: a customer with a unique email address, a document with a tracking link, a credential that should never be used. If one is ever emailed, logged into or accessed, you know data has left its home, and the canary often tells you which copy it came from.

Data Leakage Detection Tools by Category

Category What it detects Where it looks Limitations
Data discovery and classification Where sensitive data is stored Databases, file shares, cloud storage, data warehouses Finds data at rest; does not see it moving
Data loss prevention (DLP) Sensitive data leaving approved channels Email, endpoints, web traffic, cloud apps Needs tuning; noisy until rules match your data
Cloud access security broker (CASB) Risky sharing and uploads in SaaS and cloud Sanctioned and unsanctioned cloud services Coverage depends on integrations
Cloud security posture management Public buckets, open databases, misconfigurations Cloud accounts and services Shows exposure, not whether data was taken
Database activity monitoring Unusual queries and bulk reads Production and non-production databases Often deployed on production only
SIEM and behaviour analytics Anomalous access patterns across systems Logs from identity, apps, databases and cloud Only as good as the logs fed into it
External exposure monitoring Your data and credentials appearing outside Paste sites, breach forums, dark web, public repositories Finds leaks after the fact
Canary records and tokens Use or access of planted fake data Wherever the canaries are placed Only covers data sets that contain canaries

No single category covers everything. A practical baseline is discovery plus DLP plus posture management, with external monitoring and canaries added for your most sensitive data sets.

Finding Sensitive Data in Test Environments

Non-production environments are a common blind spot for detection. DLP, database activity monitoring and access reviews are usually focused on production, yet development, test, QA and UAT environments often hold full copies of production data with broader access. Extracts end up in spreadsheets, defect tickets and logs, well outside any monitoring.

  • Inventory every non-production environment, including old ones, and record what data each holds.
  • Scan non-production databases and file shares with the same discovery tools you use in production, or profile non-production data for sensitive fields as part of each refresh.
  • Test for values that should have been masked. Card numbers that pass a Luhn check, real email domains or names that match production are signs masking was skipped or failed.
  • Check where test data travels. Search defect trackers, shared drives and application logs for sensitive values.
  • Place canary records in production so you can tell if a production copy turns up somewhere it shouldn’t.

Detection tells you there is a problem; prevention stops it recurring. See our guide to preventing data leakage in test environments for the controls, RACI and refresh checklist.

What to Do When You Detect a Leak

This is general guidance, not legal advice. Follow your incident response plan and involve your privacy and legal teams.

  1. Contain it. Remove public access, revoke credentials or sharing links, and stop the data flow.
  2. Preserve evidence. Keep logs and snapshots before you change more than you need to.
  3. Assess the scope. Work out what data was exposed, whose it was, for how long and to whom.
  4. Notify where required. Many regulations set deadlines. Under GDPR, for example, a personal data breach must generally be reported to the supervisory authority within 72 hours of becoming aware of it, where feasible.
  5. Fix the root cause. Close the gap that allowed the leak, not just the instance you found.
  6. Review and improve. Add the detection rule or control that would have caught it sooner.

Data Leakage Detection Checklist

Print this section or copy it into your security runbook.

  • ☐ Sensitive data is discovered and classified across production and non-production systems.
  • ☐ DLP covers email, endpoints, web uploads and key cloud services, tuned to your classified data.
  • ☐ Database, identity, file and cloud audit logs are collected centrally and retained.
  • ☐ Behaviour analytics or alert rules flag bulk exports, unusual queries and off-hours access.
  • ☐ Cloud posture scans check for public buckets, open databases and risky sharing.
  • ☐ Code repositories are scanned for credentials and sensitive data.
  • ☐ External monitoring watches for your domains, credentials and data outside the organisation.
  • ☐ Canary records are planted in your most sensitive data sets.
  • ☐ Non-production environments are inventoried and scanned for unmasked sensitive data.
  • ☐ Access to sensitive data is reviewed at least quarterly.
  • ☐ An incident response plan covers containment, evidence, scoping, notification and root-cause fixes.
  • ☐ Every detected leak leads to a new or improved control.

Conclusion

Detecting data leakage comes down to three things: knowing where your sensitive data lives, watching how it moves and who touches it, and looking outside for signs it has escaped. Most organisations already have some of these tools. The gaps are usually coverage, particularly in non-production environments, and tuning. Close those, rehearse your response, and treat every leak you find as a lesson for the controls that should have stopped it.

TestEnvironmentManagement.com is an Enov8 resource. Links to Enov8 pages are included where they add detail or show how a product addresses the problem described.
How to Choose a Test Data Protection Method

Every team that tests with realistic data eventually faces the same question: how do we make this data safe without making it useless? There are four common answers: static data masking, tokenization, synthetic data and subsetting. Vendors tend to argue for whichever one they sell. In practice, most organisations need a combination, and the right choice depends on the environment, the data and what the tests actually need.

This guide gives you a practical way to decide. It covers what each method protects, how they compare on test realism, effort and compliance, a decision flowchart, and how to match methods to each environment.

The Four Methods at a Glance

  • Static data masking replaces sensitive values in a copy of production data with realistic substitutes and keeps no mapping back to the original. The structure, formats and relationships stay intact, so tests behave as they would in production.
  • Tokenization replaces sensitive values with tokens. In its reversible form, an authorized system can retrieve the original through a vault or a cryptographic key. It is built for production workflows that need the original back, such as payment processing.
  • Synthetic data is generated from rules, models or schemas rather than copied from production. Because no real records are involved, nothing real can leak, but realism depends on how well the generator models your data.
  • Subsetting extracts a smaller, referentially intact slice of production data. It reduces the volume of sensitive data in test, along with storage and refresh time, but it does not protect the records it keeps. Subsetting is a companion to masking, not a substitute for it.

Encryption at rest is often mentioned alongside these, but it is not a test data protection method on its own. Testers and applications see decrypted values when they use the data, so it protects the disk, not the people looking at the records.

Comparison Matrix

Criteria Static masking Tokenization (reversible) Synthetic data Subsetting
What it protects Sensitive values in the copy Sensitive values in connected systems Everything; no real records Nothing by itself; reduces how much data is exposed
Reversible? No Yes, for authorized systems Not applicable Not applicable
Test realism High; real patterns, volumes and edge cases preserved High for structure; tokens are not realistic-looking values unless format-preserving Varies; depends on the generator High for the records kept
Referential integrity across systems Yes, if masking is consistent across systems Yes, if tokens are deterministic Hard across many systems; depends on the tool Yes, if relationships are followed during extraction
Set-up effort Medium: discovery, rules, validation High: vault or key infrastructure Medium to high: modelling rules and relationships Medium: defining the slice
Ongoing effort Re-run on every refresh Operate and secure the token service Maintain generators as schemas change Re-run on every refresh
Compliance fit Strong for non-production, if the whole dataset is de-identified Strong in production; adds in-scope infrastructure to test Strongest; no personal data Helps by data minimisation; data kept is still regulated
Best for SIT, QA, UAT and performance testing Testing systems that must detokenize New features, demos, training, external partners Large estates where full copies are slow or costly

Five Questions That Decide It

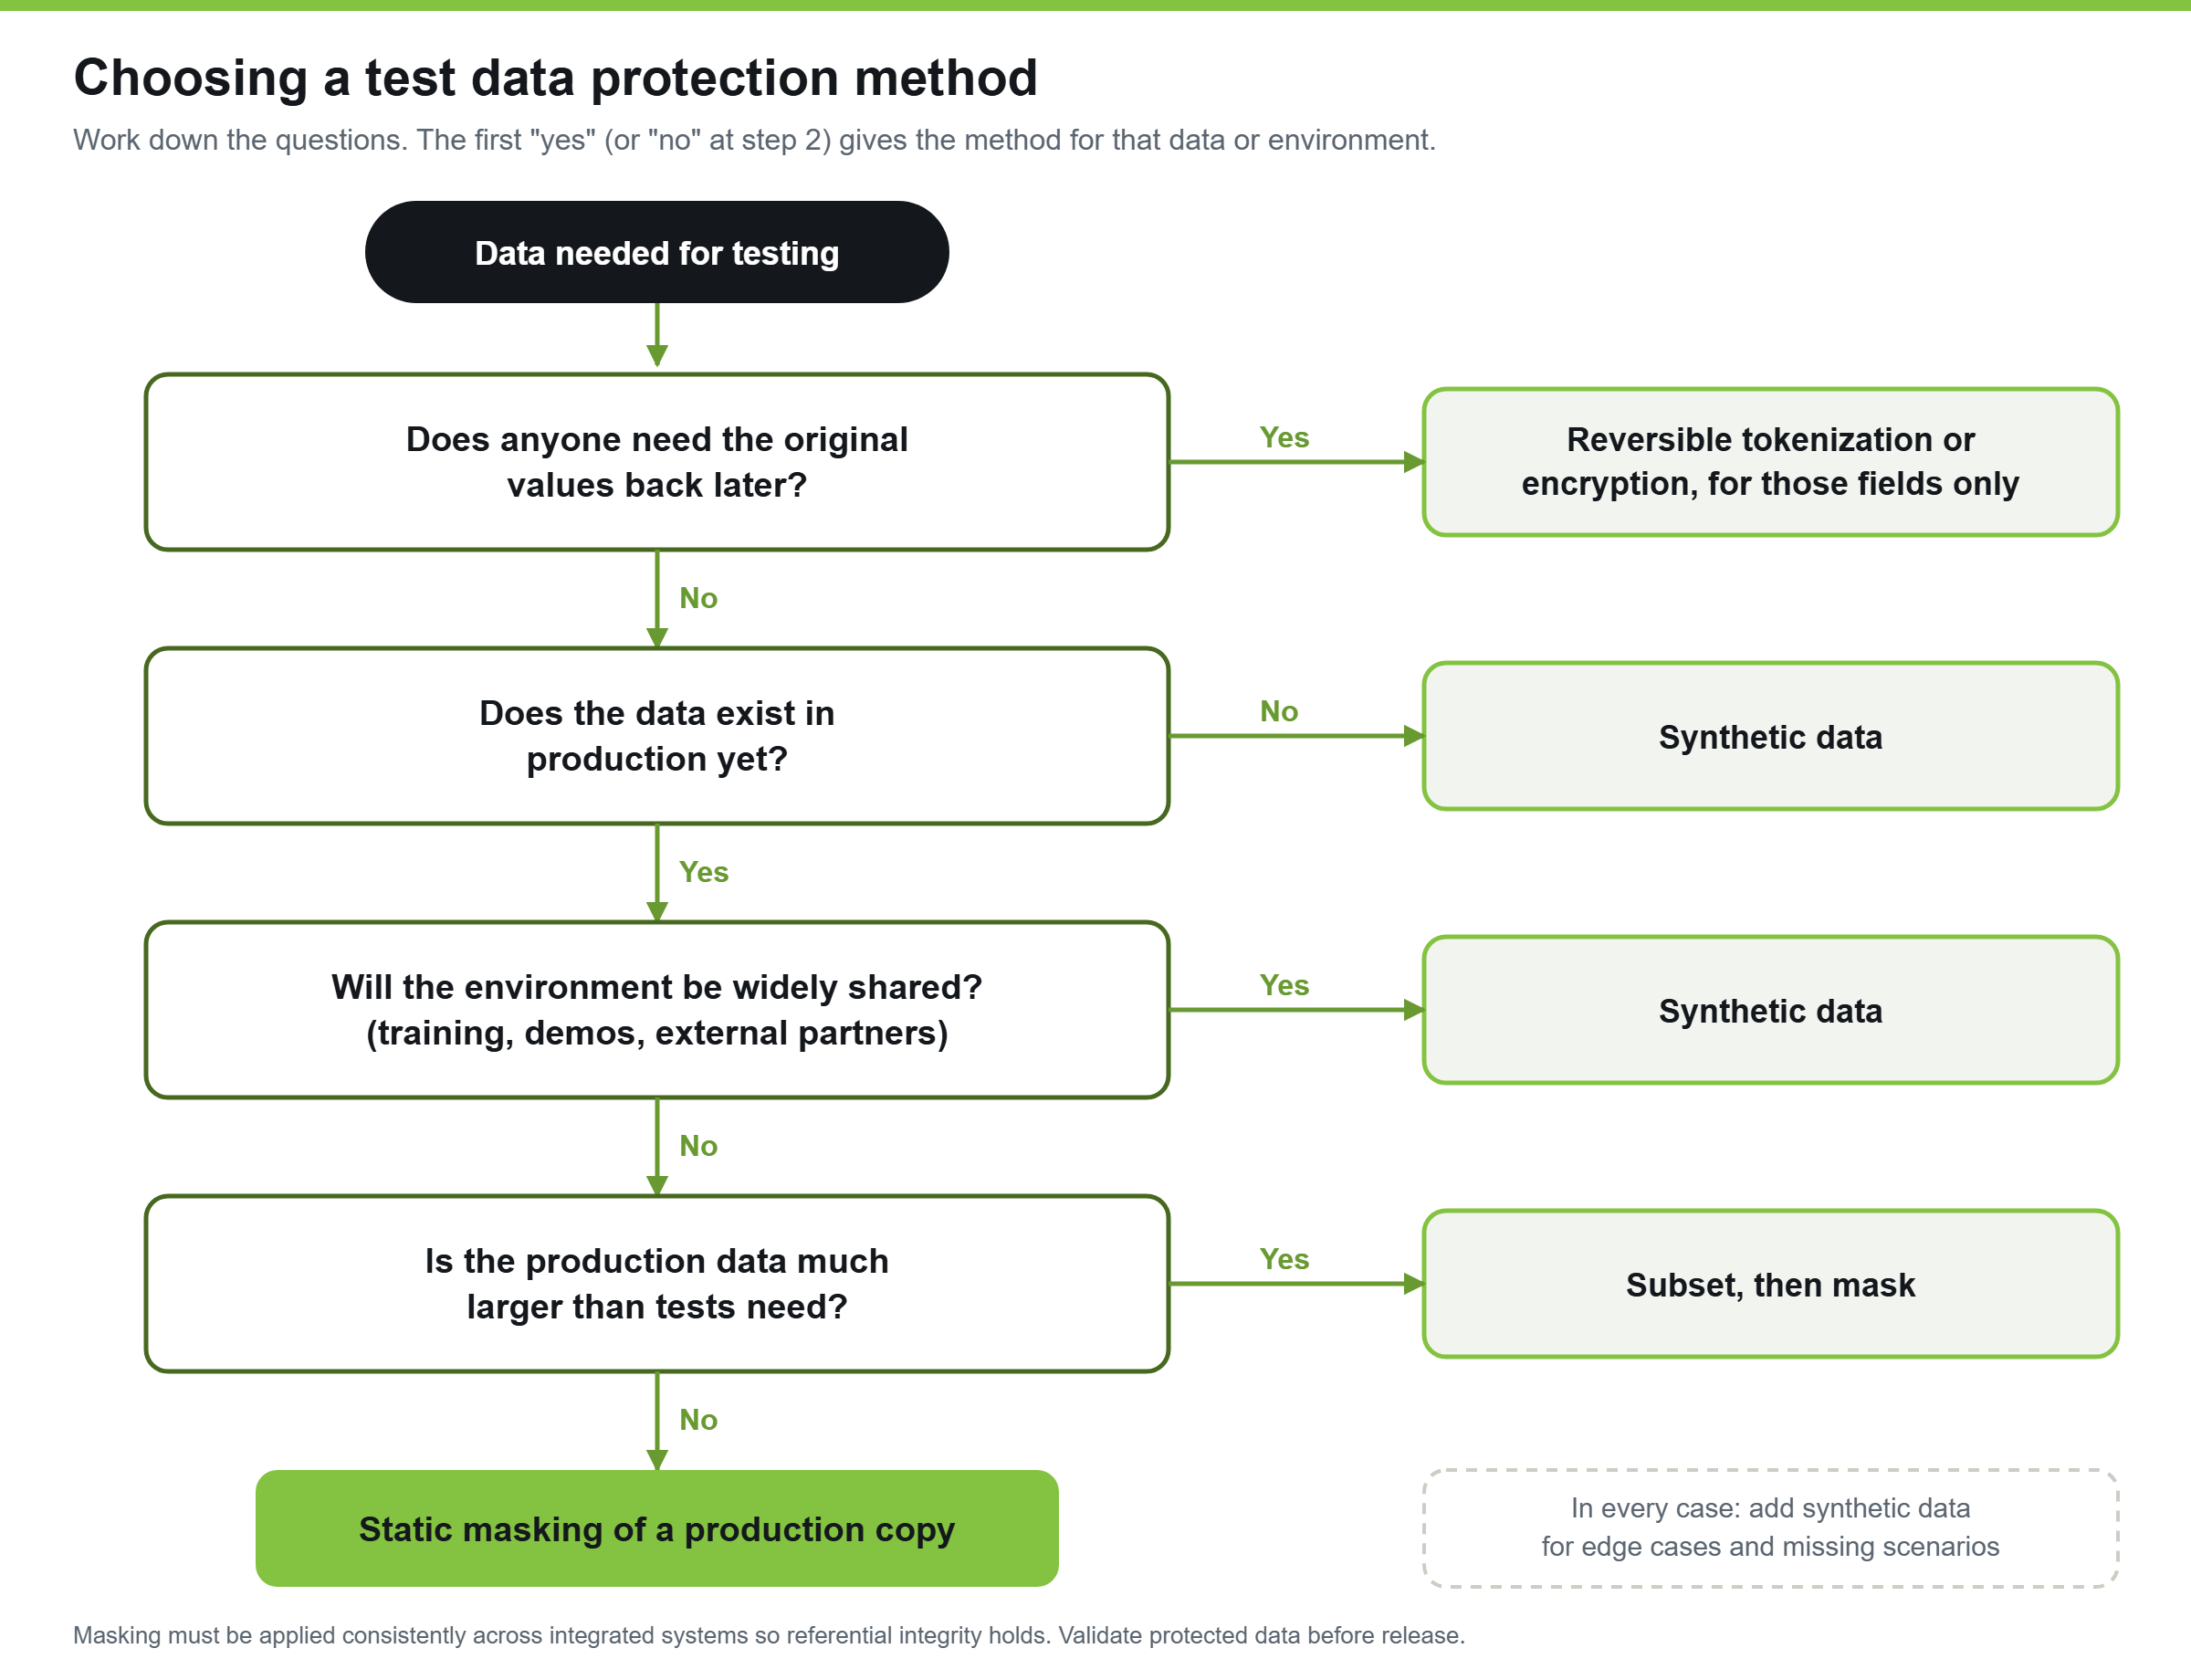
Work through these questions for each data set or environment. The flowchart below shows the same logic.

Decision flowchart for choosing a test data protection method

  1. Does anyone need the original values back later? If yes, use reversible tokenization or encryption, but only for the specific fields that need it. Everything else can still be masked.
  2. Does the data exist in production yet? If you are testing a new feature, product or data model, there may be nothing to copy. Generate synthetic data.
  3. Will the environment be widely shared? Training, demo and partner environments reach large or external audiences. Synthetic data removes the risk entirely and is usually realistic enough for these purposes.
  4. Is the production data much larger than the tests need? Subset first to a representative, referentially intact slice, then mask it. You protect less data, refresh faster and store less.
  5. Otherwise: use static masking of a production copy. It gives the highest realism for integration, regression and user acceptance testing.

Whatever you choose, add synthetic records to cover edge cases and scenarios that production data does not contain.

Matching Methods to Environments

Environment Recommended approach Why
Development Synthetic data, or a small masked subset Developers rarely need volume, and access is often broad
System and integration test Masked production copy, consistent across systems Interfaces and joins must line up across applications
QA and regression Masked subset plus synthetic edge cases Repeatable data sets with good coverage
UAT Masked production copy Business users need recognisable, realistic scenarios
Performance and load Masked full-volume copy, or synthetic data at scale Volume and distribution matter more than individual records
Training and demo Synthetic data Wide audiences and long-lived environments
Systems that must detokenize Tokenization with test-only keys or vault The application logic depends on retrieving originals

For more on where each environment leaks data, see our guide to preventing data leakage in test environments.

Masking vs Tokenization for Test Data

The key difference is reversibility. Static masking keeps no route back to the original, which is exactly what most test environments need. Reversible tokenization keeps that route, which means running and securing a vault or key service, and that service then sits inside your compliance scope. Unless an application under test genuinely needs to detokenize, masking is usually the simpler and safer choice. Enov8 has a detailed comparison of masking and tokenization, and if you do need tokenization, DataOpsZone explains how vaulted and vaultless architectures differ.

Masking vs Synthetic Data

Masked data keeps the real-world patterns, volumes and quirks of production, including the odd records that find real defects. Synthetic data carries no privacy risk and can create scenarios production never had, but it only reflects what the generator knows about your data, and keeping relationships consistent across many systems is hard. Most mature teams use masked data for integration and acceptance testing and synthetic data for development, demos and edge cases. For a deeper look, see synthetic data vs masked real data for software testing.

Common Mistakes

  • Masking each system differently. If a customer ID is masked one way in the CRM and another way in billing, integration tests break. Use consistent, deterministic rules across systems.
  • Treating subsetting as protection. A smaller copy of real data is still real data.
  • Calling encryption masking. Encrypted data that testers can decrypt has not been de-identified.
  • Tokenizing test data by default. It adds infrastructure and compliance scope that most test environments do not need.
  • Assuming synthetic data is realistic enough. Validate that it exercises the same paths and edge cases as production.
  • Protecting once and forgetting. Every refresh brings real data back unless protection runs as part of it.
  • Skipping validation. Check that no real values remain before data reaches test teams.

Conclusion

There is no single best test data protection method. Start with one question: does anyone need the original values back? For most test environments the answer is no, which makes static masking the default for realistic testing, subsetting the way to keep volumes manageable, and synthetic data the answer for new features and widely shared environments. Keep tokenization for the systems that genuinely need to reverse it.

Platforms such as Enov8 Test Data Manager and Data Factory bring these methods together, with profiling to find sensitive data, consistent masking across systems, subsetting and synthetic data generation. Learn more about Enov8 test data management, or compare options in our test data management tools comparison.

TestEnvironmentManagement.com is an Enov8 resource. Links to Enov8 pages are included where they add detail or show how a product addresses the problem described.
Preventing data leakage in test environments

Preventing Data Leakage in Test Environments: A Practical Guide

Most organisations spend heavily on protecting production data. Then, every few weeks, they copy it into development, test, QA and UAT environments, where access is broader, controls are lighter and nobody is quite sure who owns it. For many teams, the non-production estate is where sensitive data is most exposed.

This guide is for test environment, QA and platform managers who hold copies of production data. It covers where leaks actually happen in non-production, which environments carry the most risk, who should own each control, and a printable checklist you can use at your next refresh. If you need the basics first, start with what data leakage is and its common causes.

Why Test Environments Leak Data

Test environments leak for a simple reason: they hold production-grade data without production-grade protection. Teams want realistic data, because realistic data finds real defects, so production databases are cloned into lower environments. The clone keeps every customer name, card number, address and health record, but it rarely keeps the access controls, monitoring and audit trails that surround production.

Then the data multiplies. One production copy becomes a dozen across SIT, QA, UAT, performance and training environments. Each of those is shared with more people, refreshed on its own schedule and exported in pieces to spreadsheets, defect tickets and test scripts. Regulations such as GDPR, HIPAA and PCI DSS apply to personal and cardholder data wherever it sits, so a leak from a test system carries the same consequences as a leak from production.

Where Leaks Happen: An Environment-by-Environment Risk Table

Not every lower environment carries the same risk. Use this table to decide where to focus first. Ratings assume the environment holds unmasked production data.

Environment Who typically has access Common leak paths Risk Priority control
Development Developers, contractors, offshore teams Local copies on laptops, data in code repositories and logs, debugging with real records High Masked or synthetic data only; no production copies
System and integration test (SIT) Testers, developers, vendor teams, interface owners Shared service accounts, data passed to connected third-party test systems High Consistent masking across all integrated systems
QA and regression QA team, automation tools, vendors Test data in automation scripts, screenshots and defect tickets Medium to high Masked data; scrub defect attachments
UAT Business users, external testers, vendors Broad business access, extracts to spreadsheets, data shared over email High Named access, time-boxed accounts, masked data
Performance and load Performance engineers, tooling vendors Full-volume production copies, data sent to cloud load-testing tools High Masked full-volume data or synthetic data at scale
Training and demo Trainers, new staff, sales and partners Wide audiences, long-lived environments, screen sharing Medium to high Synthetic data only
Stale or orphaned environments Whoever still has credentials Forgotten databases, old backups, accounts never revoked High Inventory, expiry dates and decommissioning

Six Leak Paths to Close

1. Production refreshes that copy everything

The most common leak starts with the refresh itself. A full production clone is the fastest way to get realistic data, so it becomes the default. Every refresh then re-introduces sensitive data into environments that were never designed to hold it. If masking happens after the copy lands, there is a window where unprotected data sits in test; if it is skipped “just this once”, that window stays open.

2. Broad access and shared accounts

Lower environments often run on shared logins, generic service accounts and permissions copied from the last project. Nobody reviews them because “it’s only test”. The result is that dozens or hundreds of people can query tables full of personal data, and audit logs cannot tell you who did.

3. Contractors, offshore and third-party teams

Delivery partners, offshore testers and vendors frequently have deeper access to non-production than to production. Data may cross borders, sit on partner-managed devices or flow into vendor tools. Contracts and NDAs help, but they do not stop the data being exposed in the first place.

4. Stale and forgotten environments

Projects end; environments don’t. Old UAT databases, abandoned performance rigs and backups from retired test systems keep holding production data long after anyone uses them, often with credentials that were never revoked. They are invisible to most security reviews because nobody remembers they exist.

5. Data escaping the environment

Even a well-controlled environment leaks when data leaves it. Watch for extracts to spreadsheets, real records pasted into defect tickets and chat, screenshots in test evidence, verbose application logs, and test data pasted into public AI tools to generate scripts or analyse failures. Each copy is outside every control you put on the environment.

6. Compliance blind spots

Data protection impact assessments, records of processing and PCI scope reviews often focus on production. If test copies of personal or cardholder data are not in those records, the organisation may be out of compliance without knowing it, and a breach notification will come as a surprise.

How to Prevent Data Leakage in Test Environments

The controls that matter most are the ones that stop real data arriving in test, followed by the ones that limit who can reach it and how long it lives.

  • Protect data before it lands. Profile production data to find sensitive fields, then apply data masking or synthetic data as part of the refresh, not after it. Masking must be consistent across systems so that joins, interfaces and referential integrity still work.
  • Make masked data the default. Require an approved exception, with an owner and an expiry date, for any environment that needs unmasked data.
  • Apply least privilege. Use named accounts, role-based access and time-boxed access for contractors and vendors. Remove shared logins wherever possible.
  • Govern refreshes. Treat every refresh as a controlled change with a defined source, a masking step, validation and sign-off. See securing lower environments for the wider hardening picture.
  • Keep an environment inventory. Know every non-production environment, what data it holds, who owns it and when it expires. Decommission what is no longer used.
  • Control data leaving the environment. Set rules for extracts, defect attachments, logs and AI tools, and back them with data loss prevention tooling where you can. Our guide to detecting data leakage covers the monitoring side.
  • Measure it. Track the share of environments holding masked data, open exceptions and refresh lead times. Our guide to test data management metrics has more ideas.

Who Owns This: A Simple RACI

Leaks in non-production often happen because everyone assumes someone else is responsible. Adapt this RACI to your organisation. R = Responsible, A = Accountable, C = Consulted, I = Informed.

Activity Data owner Test environment manager Test data manager Security and privacy Delivery teams and vendors
Classify sensitive data and set protection rules A I R C I
Mask or generate data during refresh I C A / R C I
Validate protected data before release C I A / R C I
Grant, review and revoke environment access C A / R I C I
Approve exceptions for unmasked data A C C R I
Maintain inventory and decommission environments I A / R C I C
Follow data handling rules (extracts, tickets, AI tools) I C I A R
Respond to a suspected leak C R R A C

Printable Checklist: Preventing Data Leakage in Test Environments

Print this section or copy it into your refresh runbook.

Before each refresh

  • ☐ Sensitive fields are identified and classified for every source system in scope.
  • ☐ Masking or synthetic data rules are defined, approved and versioned.
  • ☐ The same rules are applied across all integrated systems to preserve referential integrity.
  • ☐ Any request for unmasked data has an approved exception, an owner and an expiry date.

During the refresh

  • ☐ Data is masked before it is made available to test users.
  • ☐ Protected data is validated, with no real values remaining in sensitive fields.
  • ☐ The refresh is logged with source, date, rules applied and sign-off.

While the environment is in use

  • ☐ Access uses named accounts and role-based permissions; no shared logins.
  • ☐ Contractor, offshore and vendor access is time-boxed and reviewed.
  • ☐ Rules for extracts, defect attachments, logs and AI tools are published and followed.
  • ☐ Access is reviewed at least quarterly, and leavers are removed promptly.

Ongoing governance

  • ☐ Every non-production environment is in the inventory with an owner, data classification and expiry date.
  • ☐ Test copies of personal and cardholder data are included in privacy and compliance records.
  • ☐ Unused environments, databases and backups are decommissioned and securely deleted.
  • ☐ There is a documented response plan for a suspected leak from non-production.

Conclusion

Data leakage in test environments is rarely the result of a sophisticated attack. It comes from routine refreshes, broad access, forgotten environments and data copied out for convenience. The most effective control is also the simplest: stop real sensitive data from reaching non-production, then govern access and lifecycle for everything that remains.

If your refreshes still copy raw production data, tools such as Enov8 Test Data Manager can help you profile, mask production data before it reaches test, and validate the result, so teams keep realistic data without the exposure. For a broader view of the options, see our test data management tools comparison.

TestEnvironmentManagement.com is an Enov8 resource. Links to Enov8 pages are included where they add detail or show how a product addresses the problem described.